The Leader in Smart AI-Native Data

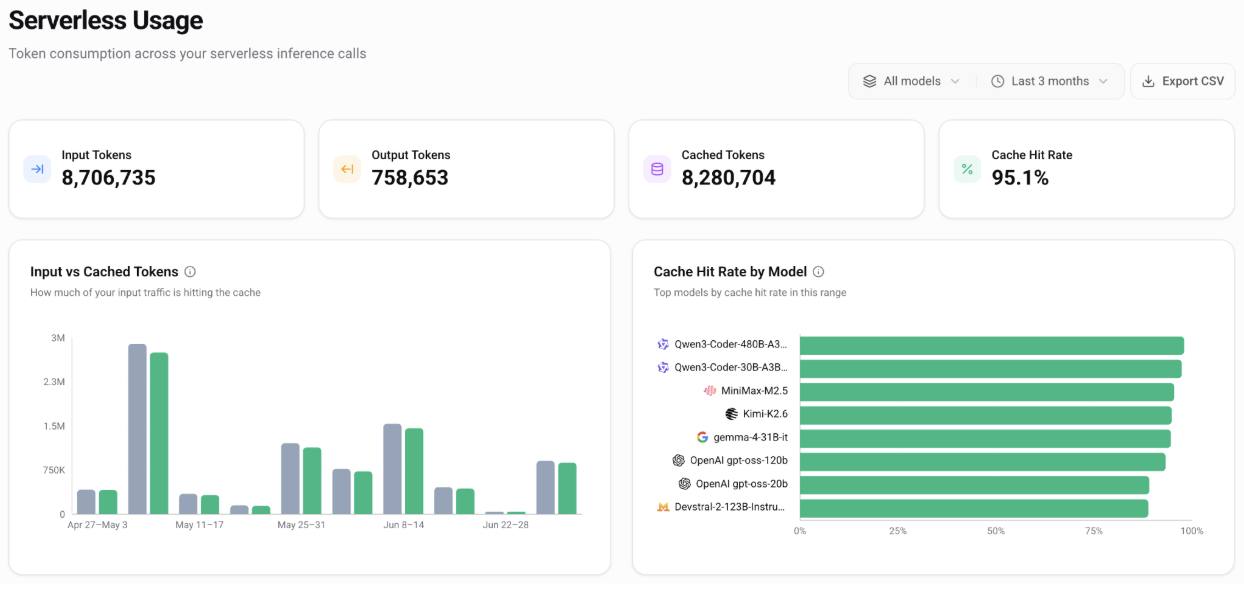
Tensormesh Platform is a Data Management Layer for AI Inference. The platform enables a multi-tier scalable KV Cache that rapidly reduces miss rate and significantly cuts GPU recompute, addressing AI data challenges related to efficiency, cost, and quality. The solution becomes the foundation of the enterprise's AI intelligent data, available to operators and agents to manage, analyze, and optimize.

Tensormesh Platform

As Enterprise deploy AI workload in Self Hosted Infrastructure, the Tensormesh Platform addresses the following challenges:
AI Data Sovereignty
Data Retention in Regulated Environment
Cost Reduction
Performance Optimization
Sustainability
Reviews

Trusted by teams scaling AI workloads

Enterprises everywhere are wrestling with the huge costs of AI inference, Tensormesh’s approach delivers a fundamental breakthrough in efficiency and is poised to become essential infrastructure for any company betting on AI.

Ion Stoica

Co-Founder, Databricks

Tensormesh enabled distributed KV-cache sharing across servers—delivering performance that exceeded expectations.

Rowan T.

CEO

The LMCache team rapidly adapts and delivers results that stabilize and optimize model hosting. It’s a major step forward for enterprise LLM performance.

Prashant P.

Software Engineer

Our collaboration with LMCache accelerated our GDS open-source release and achieved a 41× reduction in time-to-first-token—transforming large-scale AI economics.

Callan F.

Product Lead

We’ve seen major LLM efficiency and cost savings using the vLLM Production Stack from Tensormesh’s founders.

Ido B.

CEO
Blog & News

Explore latest news & insights

July 23, 2026

Tensormesh and AMD Collaborate to Empower Fewer GPUs to Serve More Models

Read Now

May 27, 2026

Tensormesh Raises $20M from Investors Including AMD Ventures, CoreWeave, NVentures, Launches Tensormesh Inference to Fix AI’s Most Expensive Problem

Read Now

October 23, 2025

Tensormesh Emerges From Stealth to Slash AI Inference Costs and Latency by up to 10x

Read Now

August 18, 2026

Building Production AI Infrastructure: Lessons from AI at Hyperscale

Read article

July 30, 2026

Why LLM Inference Is a Data Problem, Not Just a Compute Problem

Read article

July 1, 2026

Designing AI Infrastructure Products for Developers

Read article

Make repeated context work for you

Test your workload, measure the savings, and see how much cached-token pricing can reduce your bill.

Talk to an engineer

Have questions about our billing formula?

Read the Docs